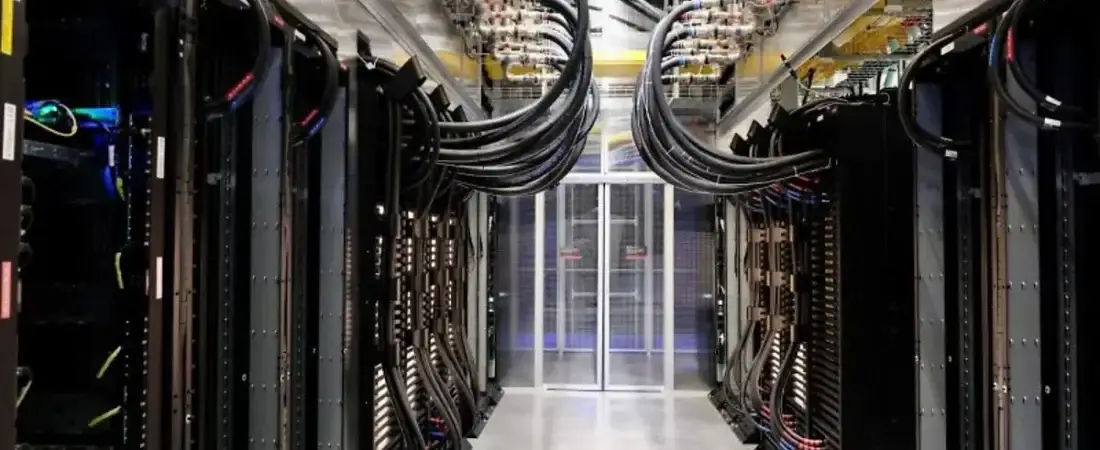
NVIDIA AI server prices are reportedly set to rise by more than 15% for some configurations, adding another cost pressure for data center operators already facing enormous capital requirements for power, cooling, networking, and accelerated computing. The reported changes would affect systems incorporating the company’s latest AI hardware, including Vera Rubin and Grace Blackwell configurations.
Reuters reported on August 22, citing Bloomberg News, that NVIDIA had informed major customers about increases expected to affect systems shipping in early 2027. Rising memory costs were reported as the primary driver.
NVIDIA had not publicly commented on the reported increases at the time of the report. That distinction matters: the pricing changes should currently be treated as reported customer notifications rather than a formal public NVIDIA pricing announcement.
Executive Summary
- Some NVIDIA-powered AI server configurations could reportedly cost more than 15% more.
- The changes are expected to affect systems shipping in early 2027.
- Vera Rubin and Grace Blackwell configurations are among the systems cited.
- The exact increase may vary by chip generation and memory configuration.
- Rising memory costs are reported to be the primary driver.
- CIOs should evaluate useful compute output and total infrastructure cost, not server acquisition price alone.
What Has Been Reported About NVIDIA AI Server Prices
According to the report, server manufacturers supplying major data center operators including Microsoft, Google, and Oracle have passed pricing information to customers.
The increases are expected to exceed 15% for some configurations, although the exact change will depend on the chip generation and memory configuration. The headline percentage should therefore not be interpreted as a uniform increase applying to every NVIDIA accelerator or server platform.
The reported timing is also important. Higher NVIDIA AI server prices are expected to affect systems shipping in early 2027, giving hyperscalers and other infrastructure buyers a relatively short period in which to reassess capital budgets for upcoming deployments.
Memory Is Becoming a Larger AI Infrastructure Constraint
The reported increase illustrates how AI infrastructure economics extend well beyond the GPU itself. Modern accelerators require large quantities of high-performance memory capable of feeding data to increasingly powerful processors. As systems become larger, memory capacity and bandwidth become critical to maintaining accelerator utilization.
That creates pressure throughout the semiconductor supply chain. For data center buyers, the practical consequence is that an accelerator roadmap cannot be evaluated solely through improvements in compute performance.
The cost and availability of memory, networking, storage, power equipment, cooling infrastructure, and server components all contribute to the real cost of deploying an AI cluster. The market is increasingly rewarding organizations that can coordinate these resources rather than procure each one in isolation.
NVIDIA AI Server Prices Add to Full-Stack Costs
Any increase in server pricing arrives at a difficult point for infrastructure buyers. Large AI deployments increasingly require substantial investment before the servers themselves are installed.
Developers may need new substations, utility upgrades, onsite generation, closed-loop liquid-cooling systems, high-speed network fabrics, and purpose-built data halls capable of supporting very high rack densities.
The largest projects are also securing land and electricity years before compute capacity becomes operational. This means a 15% or greater increase in some server configurations does not occur in isolation. It sits on top of an infrastructure stack whose cost is already rising as AI deployments become larger and more technically demanding.
Our analysis of power-led data center site selection explains why apparently inexpensive markets can still become costly when grid connections, generation, and project timelines are included.
Why the Report Matters for CIOs
For CIOs and CTOs planning AI capacity, the immediate issue is budget predictability. Enterprise strategies frequently assume that successive hardware generations will deliver more compute for a given level of capital expenditure.
Rapid performance improvements can support that assumption, but component shortages and supply-chain inflation can move costs in the opposite direction. Organizations planning 2027 deployments may therefore need to revisit assumptions around server acquisition, cloud consumption, depreciation cycles, and the timing of infrastructure purchases.
The calculation should focus on useful computing output rather than acquisition cost alone. A newer system can still deliver better economics despite a higher purchase price if it completes workloads faster, improves energy efficiency, reduces the number of servers required, or supports larger models within the same infrastructure footprint.
Conversely, paying a premium for the newest architecture makes less sense if the organization’s workloads cannot use the additional performance effectively.
Vera Rubin Raises the Infrastructure Stakes
NVIDIA’s Rubin generation represents more than another GPU refresh. The official NVIDIA Vera Rubin platform overview describes a multi-rack, pod-scale system that combines five purpose-built rack-scale systems into a coherent AI supercomputer.
That approach increasingly ties server purchasing decisions to the wider data center environment. Higher-density systems can require changes to electrical distribution and liquid cooling. Faster accelerators place greater pressure on scale-up and scale-out networks, while large memory configurations affect both performance and system economics.
Infrastructure teams therefore need to model the complete deployment rather than treating the server purchase as an isolated procurement decision. The facility demands are closely connected to the AI factory operating model.
Cloud Providers Face the Same Cost Pressure
The reported customer list is significant because it includes some of the world’s largest cloud and data center operators. Hyperscalers purchase AI infrastructure at enormous scale, but they are not immune to higher component costs.
If hardware acquisition becomes more expensive, providers can absorb the cost, improve utilization, extend depreciation periods, redesign infrastructure, or pass some of the increase to customers through AI compute pricing.
It is too early to conclude that the reported NVIDIA server increases will produce higher cloud GPU prices. Cloud pricing depends on many factors beyond hardware acquisition, and the providers named in the report have not announced corresponding customer price increases.
Enterprise buyers should nevertheless watch the relationship carefully, particularly when comparing owned infrastructure with cloud and sovereign-cloud capacity strategies.
Infrastructure Efficiency Becomes More Valuable
Higher NVIDIA AI server prices strengthen the business case for extracting more useful work from every installed system. GPU utilization can be affected by networking bottlenecks, storage performance, workload scheduling, software efficiency, cooling constraints, and power availability.
A cluster containing expensive accelerators but suffering from poor utilization can destroy the economics that justified purchasing the hardware. For data center managers, this means facility and IT optimization become financially connected.
Reliable liquid cooling can prevent thermal limitations. High-performance 800G Ethernet networks can reduce time spent waiting for data. Appropriate power architecture can support high-density racks without creating stranded capacity.
When the hardware becomes more expensive, inefficiency becomes more expensive with it.
7 Critical Actions for 2027 AI Buyers
- Reprice planned configurations. Request updated quotes by chip generation, memory capacity, networking, and delivery window.
- Model total deployed cost. Include electrical, cooling, network, storage, construction, software, and support costs.
- Measure useful output. Compare systems using workload throughput, utilization, energy use, and time to completion.
- Stress-test the schedule. Calculate the impact of delayed deliveries, commissioning, or grid energization.
- Evaluate cloud alternatives. Compare owned capacity with reserved and on-demand services using realistic utilization assumptions.
- Protect cluster utilization. Remove networking, storage, cooling, and scheduling bottlenecks before adding accelerators.
- Maintain procurement flexibility. Avoid committing every workload to one hardware generation before performance and economics are validated.
What Happens Next for NVIDIA AI Server Prices
NVIDIA’s financial results and future platform disclosures will be watched for evidence about component costs, supply constraints, and demand for its newest systems.
Buyers will also need to determine whether the reported increases remain concentrated in particular high-memory configurations or become part of a broader movement in AI infrastructure pricing. Memory supply will be particularly important.
If demand continues to grow faster than manufacturing capacity for components required by advanced accelerators, server pricing could remain under pressure even as semiconductor vendors expand production.
Frequently Asked Questions
Are NVIDIA AI server prices officially increasing?
Reuters, citing Bloomberg News, reported that major customers had been notified of increases exceeding 15% for some systems. NVIDIA had not publicly confirmed the reported changes at the time of that report.
Which NVIDIA systems could be affected?
The report cited systems using Vera Rubin and Grace Blackwell hardware. The precise increase is expected to vary according to chip generation and memory configuration.
When could higher prices take effect?
The reported increases are expected to affect systems shipping in early 2027. Buyers should confirm pricing and delivery terms directly with their server manufacturer or supplier.
Will cloud GPU prices also rise?
No corresponding cloud price increases had been announced by the named providers at the time of the report. Cloud pricing depends on hardware costs, utilization, depreciation, energy, competition, and other commercial factors.
Conclusion
The reported increase in NVIDIA AI server prices is not yet a formal public pricing announcement from the company, and the precise impact will vary by system and memory configuration.
However, the report points to a broader issue that data center leaders cannot ignore. The economics of AI infrastructure are determined by an increasingly interconnected supply chain. GPUs matter, but so do memory, networking, power, cooling, land, construction, and the equipment required to bring the entire system online.
For CIOs planning 2027 deployments, the most useful response is not simply to ask whether server prices are rising. It is to calculate how much productive AI compute the complete infrastructure investment will deliver.